EstateLens
EstateLens turns an address, listing or document into a source-linked UK property research report: recorded facts, declared gaps and category-aware conflicts, with no valuation, no score and no ranking.
O tym modelu
Description
Product Overview
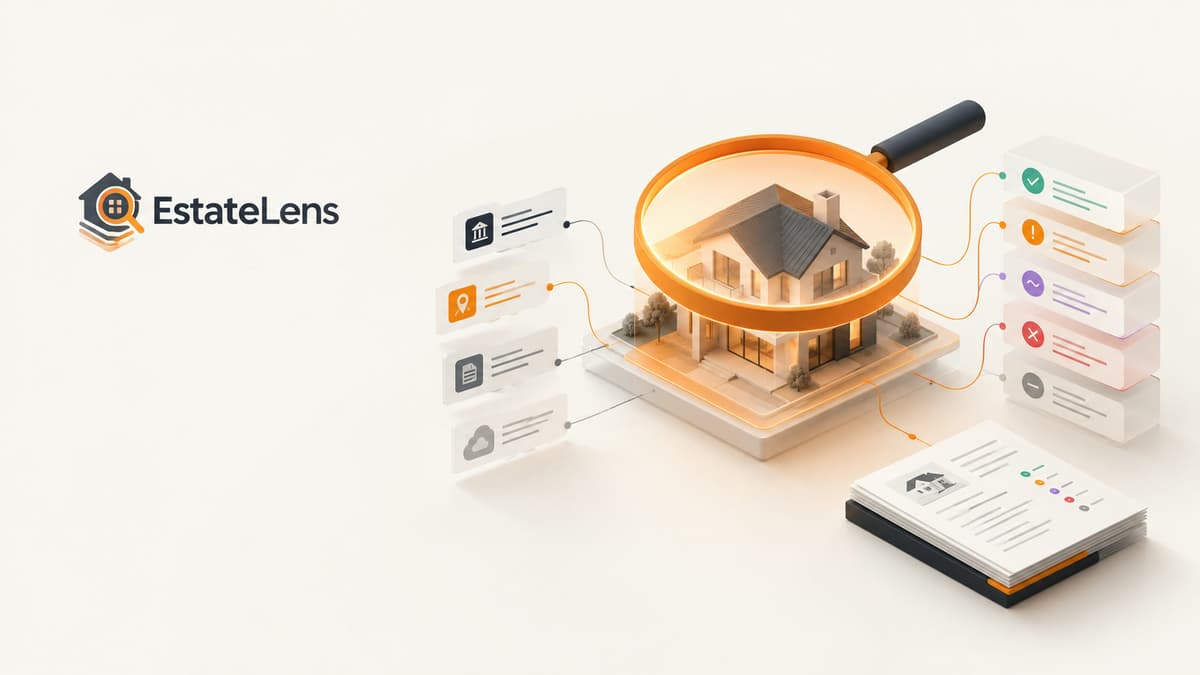
EstateLens is a property research platform for the United Kingdom that turns an address, a listing or a document into a source-linked research report, and states plainly what it could not establish. It sits in the property data and due-diligence category, between a listings portal and a professional survey: it does not appraise, value or score a property, it reconstructs the evidence around it.
The product is designed for buyers doing their own due diligence, owners reviewing a property they already hold, and small professional teams — research, advisory and conveyancing-support functions — who need a traceable file rather than confident prose. It is also exposed as an API for platforms that want evidence-linked property research inside their own workflow.
The operational problem is fragmentation and false equivalence. Property facts arrive from portals, government registers, PDFs and spreadsheets; they are different kinds of claim, yet they are read side by side. An asking price drifts into a "valuation", and a missing record is read as "nothing to worry about". EstateLens keeps those categories apart, attaches a basis and a source to every value, and converts the absence of evidence into a stated gap with a reason rather than a silent blank.
The result is a research run rather than a search box: jurisdiction identified, property identity resolved, connected sources consulted, history reconstructed, conflicts separated by category, and a versioned report retained with an evidence ledger and a correction trail.
The Problem
Property research is assembled by hand, from sources that were never designed to be compared.
A typical file is a pile of tabs: an agent's advertisement, a portal listing, a government register the analyst has to know exists, a PDF supplied by a counterparty, and a spreadsheet where the numbers are eventually reconciled. Each of those sources speaks a different dialect. An asking price is a seller's advertisement. A recorded sale price is a completed transaction published by a registry. A floor area in a listing may be measured to a different convention from the one in a document. The numbers look interchangeable and are not.
Three failures follow from that, and they are the ones the product is built around.
Category collapse. An asking price is placed beside a recorded sale and the comparison quietly produces a "value". Nothing in the workflow marks that the two figures describe different things at different times. The error is not arithmetic — it is categorical, and it survives review because the spreadsheet looks consistent.
Absence read as negation. When a register returns nothing, the file says nothing. A reader concludes the property is unremarkable. In practice, no record may mean the dataset was never loaded for that area, the source is not integrated for that market, access is not permitted, or the search genuinely found nothing — four different facts with four different consequences, collapsed into one blank cell.
Unattributable conclusions. Months later, nobody can say where a figure came from, what kind of claim it was, or whether it was ever checked. The research cannot be defended, repeated or corrected, so it is redone from scratch — or trusted because it is familiar.
Around those failures sit the ordinary costs: analyst time consumed by assembly rather than judgement; inconsistent methods between colleagues; knowledge that leaves with the person who built the file; and exposure created when a decision is taken on a number that was never what it appeared to be.
Existing tools do not resolve this by adding another dashboard. Portals optimise for discovery and advertising. Registers optimise for publication, not interpretation. The gap is a layer that records provenance, classifies claims and reports gaps — and that refuses to manufacture the confidence the underlying data does not support.
How the Product Solves the Problem
EstateLens replaces assembly-by-hand with a structured research run and a report that carries its own audit trail.
A run begins with a subject: an address, listing details the user enters, a page on a host the operator has explicitly allowlisted, or a document the user is entitled to use. The run identifies the jurisdiction, resolves the property's identity, and consults only the sources that are actually connected for that market. Where it needs more — which UK nation applies, what tenure is acceptable — it asks, and the answers continue the same run rather than restarting it.
Every value that comes back is recorded with two things: its basis (official record, licensed data, claim, estimate, inference, conflicting or unavailable) and its source, with the date of last observation. The report does not present a flat table of facts. It presents a ledger in which the difference between a register entry and a seller's assertion is structurally visible.
Conflicts are separated by category rather than counted. Two advertisements disagreeing about price is informational. Two registry records disagreeing about the same transfer date is material. A small floor-area difference is measurement variation; a large one is a finding. An asking price is never compared with a recorded sale as if the comparison meant something.
Gaps are the product's most deliberate output. A section that could not be produced says which condition applies: no source integrated for that market, access not permitted, the source returned nothing, or the dataset not loaded. The report never converts "we could not check" into "there is nothing there".
Where an official sales dataset has been imported by the operator, comparable completed sales are returned for the same postcode with their dates, tenure and comparability notes — and with the plain statement that current availability is unknown, because there is no licensed listing feed. Nothing in the product represents a home as being for sale.
Interpretation, where enabled, is optional and constrained: a model-assisted summary is generated through a single audited gateway and checked before display, so that every claim must cite evidence that exists and every number must appear in that evidence. Claims that fail the check are discarded and counted, and the count is visible in the report. The model never creates an evidence row.
Problem-Solving Flow
Value Creation Model
Value is created by changing what a research file is: from a collection of numbers whose provenance has been lost, to a classified, attributed and versioned record that can be reviewed, corrected and reused.
The economic mechanism is not automation of a single task. It is the removal of three recurring costs that sit underneath most property research: the cost of assembling evidence by hand, the cost of decisions taken on misclassified data, and the cost of research that cannot be repeated because nobody recorded how it was produced.
Value Creation Table
Key Benefits
The benefits below describe what changes for the customer, not what the software contains. Each is grounded in behaviour the product actually exhibits: basis-labelled evidence, category-aware conflict handling, declared gaps, a persistent ledger, and an auditable correction trail.
Benefits Table
Before vs. After
The transformation is operational rather than cosmetic. The subject matter does not change — the same property, the same registers, the same documents — but the file produced around it changes from an assembly of assertions into a classified, attributed record.
Transformation Table
Customer Journey
EstateLens fits into the due-diligence lifecycle at the point where evidence is gathered and must later be defended. It is deliberately positioned before professional services — a survey, a valuation, a legal opinion — so that the user arrives at those engagements knowing what is established and what still has to be commissioned.
Operational Flow
Who Benefits
Adoption is usually bottom-up: one analyst or one buyer starts using it on live files, and the persistent ledger becomes the reason a team standardises on it. The value differs by role, but the common thread is that each role needs to know what is established and what is not.
Customer Value Table
Business Impact
Impact is described as potential, because the size of the effect depends on the customer's volume, workflow and existing method. Nothing below assumes a measured result.
Business Impact Table
Strategic Value
EstateLens is built as an evidence layer rather than a destination website, and that shapes its strategic value.
Consolidation without false unification. It replaces a set of ad-hoc research artefacts with one structure, while keeping the underlying sources distinguishable — a consolidation of method, not a pretence that all data is equivalent.
A coverage model that can be inspected. Coverage is governed by a source registry with explicit statuses: implemented, import-only, contract required, not implemented, prohibited, and implemented but unverified live. A market is not described as supported because a URL parses. That registry is the mechanism by which coverage can be expanded honestly and reviewed by the customer.
An operating model for new sources. Adding a source is a governed act with licence terms and a status, not a scraping job. That makes the platform extensible into new datasets and jurisdictions without quietly degrading the meaning of the output.
Institutional knowledge that compounds. The evidence ledger, correction history and versioned reports accumulate into a record of what was known about a property and why — an asset that survives staff turnover and can be reused in later transactions.
Future-readiness. The product is designed to state its own limits: where a source is not integrated, it says so. That property is what allows the platform to add capability over time without retroactively invalidating the assumptions behind earlier work.
Differentiation
Refusal is designed in, not bolted on. The product does not produce a valuation, a price opinion, a score, a ranking or an investment recommendation, and the report is explicit about that. For professional workflows this is a feature: the research can be used alongside valuation and legal advice without being mistaken for either.
A basis taxonomy on every value. Official record, licensed data, claim, estimate, inference, conflicting and unavailable are first-class categories attached to each value and each source. The distinction between what a register says and what a seller asserts is structural, not editorial.
Category-aware conflict handling. Conflicts are interpreted by what they mean: price advertisements disagreeing is informational, registry records disagreeing on a transfer date is material, and an asking price is never compared with a recorded sale. This is the specific error most property spreadsheets make, and it is the one the product is built to prevent.
Coverage is a registry, not a promise. The product publishes the status of each of its sources and the reason a market or section is unavailable, including sources that are registered but not operational. Customers can see what the platform knows, and what it does not.
Traceability as a retained record. Corrections are audit-logged, report versions are kept, and the evidence ledger persists per property — so research can be reviewed, defended or re-run with the original basis intact.
Constrained interpretation. Where model-assisted text is enabled, it must cite evidence that exists and use only numbers present in that evidence; failures are discarded and counted in the report. Interpretation accelerates reading without creating unattributed claims.
Why It Matters
Property decisions are made on evidence that is scattered, heterogeneous and easy to misread. The cost of that is not usually a dramatic failure; it is a quiet accumulation of conclusions that were never quite what they appeared to be — a price that was an advertisement, a blank that was an unloaded dataset, a file nobody can reconstruct six months later.
EstateLens addresses that at the level where it actually happens: the classification and provenance of each value, and the honesty of each gap. It converts a property file into a source-linked record, applies consistent rules to what counts as evidence, and states what it could not establish instead of filling the space.
The commercial consequence is straightforward. Teams get specialist time back from assembly, decisions rest on correctly classified evidence, risk surfaces before commitment rather than after it, and the research itself becomes a durable, reviewable asset. For organisations that need property research they can defend, that combination — evidence discipline first, automation second — is the difference between a faster version of the old workflow and a genuinely more reliable one.
Kluczowe funkcje
Przypadki użycia
- Buyer due diligence on a specific property before commissioning a survey, valuation or legal opinion
- Owner review of the recorded and advertised history of a property already held
- Traceable research files for small advisory and research teams
- Evidence-based comparison of 2-4 candidate properties without a synthetic score
- Embedding evidence-linked property research into an existing platform via API
Plany cenowe
Plany cenowe
Powiązane produkty

CallQA 100
Automated QA scorecards, script compliance, empathy metrics & churn risk analysis for 100% of contact center calls in seconds.

BoatSurvey Snap
Pre-Purchase Boat Photo & Audio Survey for Buyers, Insurers & Marinas — instant hull blister, corrosion, and engine bay inspection.

BlueprintTakeoff AI
Construction Quantity Takeoff from Plan PDFs and Photos in Minutes — instant materials, wall/slab takeoffs, and cost estimates.