SensiAvera
Enterprise Global Intelligent Document Understanding & Visual PII Redaction Platform processing 29 document categories across 45+ jurisdictions.
Informazioni su questo modello
1. Product Overview
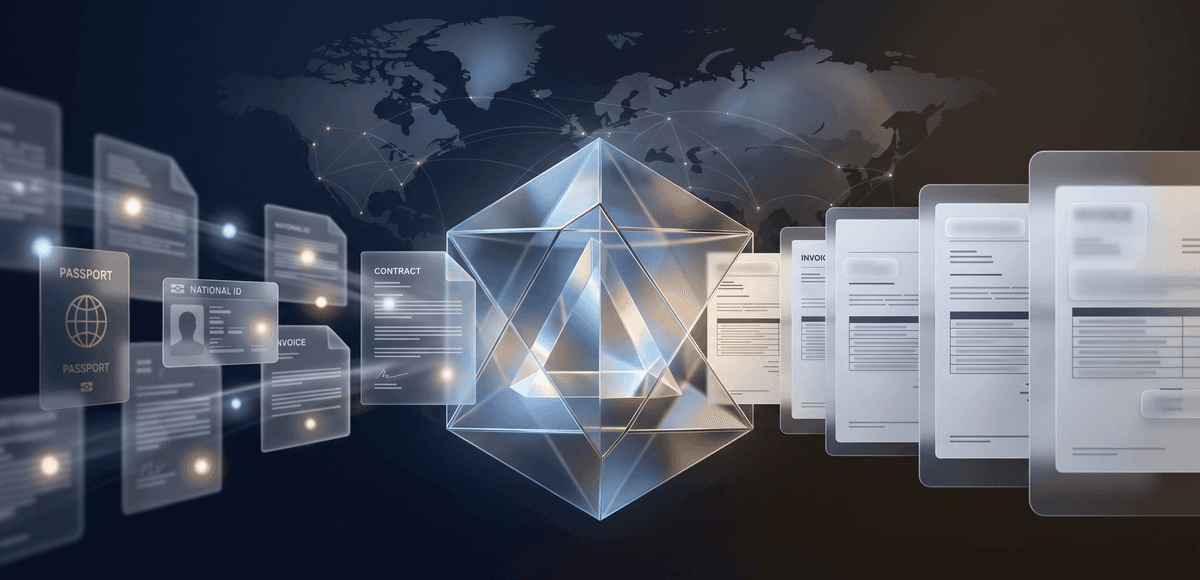
SensiAvera is an enterprise-grade Global Document Intelligence and Automated Redaction Platform engineered to streamline, validate, and secure high-volume document workflows across global jurisdictions. Purpose-built for multinational enterprises, financial institutions, cross-border logistics operators, healthcare organizations, and high-growth B2B platforms, SensiAvera eliminates the operational friction, manual costs, and regulatory risks associated with processing complex international documentation.
Operating across 45+ geopolitical jurisdictions and 29 specialized document categories—ranging from government-issued identity credentials and civil status records to complex logistics declarations, financial statements, and commercial contracts—SensiAvera provides an end-to-end document understanding lifecycle. The platform automates document intake, regional classification, spatial entity extraction, mathematical checksum verification, policy-driven visual obfuscation, and structured compliance audit logging into a unified operational workflow.
2. The Business Problem
Global organizations face mounting friction when handling unstructured and semi-structured documents sourced across international markets:
- Geopolitical & Topological Fragmentation: Document layouts, official nomenclatures, and language conventions vary widely across jurisdictions. A commercial tax invoice, identity card, or customs declaration in Europe adheres to entirely different structural norms, regex patterns, and validation rules than corresponding documents in North America, the Middle East, or the Asia-Pacific region.
- Costly & Error-Prone Manual Processing: Relying on manual data entry and human verification creates severe operational bottlenecks, delays customer onboarding, and introduces transcription errors that ripple through downstream enterprise systems.
- Escalating Data Privacy & Regulatory Penalties: Global privacy mandates—including GDPR, UK GDPR, HIPAA, CCPA, and regional Personal Data Protection Laws (PDPL)—impose strict penalties for the unauthorized exposure of Personally Identifiable Information (PII) and sensitive corporate records. Manual redaction is inconsistent, labor-intensive, and prone to catastrophic oversights.
- Inadequate Verification Mechanisms: Standard optical character recognition engines extract raw text without verifying whether the extracted identifiers are mathematically authentic. Transcription mistakes and optical distortions frequently result in unverified records entering core transactional databases.
Left unaddressed, these challenges produce surging back-office operational expenses, extended processing lead times, diminished customer satisfaction, and heightened vulnerability to regulatory sanctions and data breach liabilities.
3. How the Product Creates a Solution
SensiAvera transforms disjointed, manual document processing into an intelligent, highly automated, and auditable enterprise pipeline:
- Intelligent Ingestion & Multi-Jurisdiction Classification: SensiAvera ingests incoming documents across heterogeneous formats (multi-page PDFs, high-resolution scans, mobile captures) and instantly determines the country of origin, issuing authority, document category, and layout version.
- High-Fidelity Entity Extraction with Spatial Grounding: The platform extracts critical metadata fields alongside their exact visual bounding coordinates, normalized data values, extraction confidence scores, and contextual reasoning.
- Deterministic Mathematical & Checksum Validation: Rather than accepting extracted text at face value, SensiAvera subjects critical identification numbers, bank routing codes, tax registries, and transit numbers to rigorous mathematical checksum algorithms. This eliminates optical hallucination and ensures only valid records pass downstream.
- Policy-Driven Visual Redaction & Metadata Sanitization: Organizations can establish granular data protection policies based on PII classification levels (Critical, High, Medium, Low). SensiAvera applies permanent visual obfuscation across validated pixel regions and purges hidden document metadata before output files are distributed.
- Human-in-the-Loop Exception Management: For edge cases or extractions falling below custom confidence thresholds, documents are automatically routed to a dedicated review queue, enabling subject-matter specialists to inspect, approve, or adjust field values seamlessly.
- Multi-Format Data Delivery & Enterprise Audit Governance: Extracted datasets and sanitized documents are exported in structured formats (JSON, CSV, searchable PDF, redacted PDF) alongside tamper-evident audit logs capturing every processing event.
4. Problem-to-Outcome Flowchart
5. Value Creation Model
6. Key Business Benefits
7. Before vs. After
8. Customer Workflow
- Intake & Ingestion: Documents are ingested through web uploads, batch folders, or upstream API integrations, supporting images and multi-page PDFs.
- Automated Classification: SensiAvera analyzes visual geometry, language anchors, and layout structures to classify the document category and country of origin.
- Precision Extraction: The system identifies key entities, values, spatial bounding boxes, and field-level confidence ratings.
- Algorithmic Validation: Critical identifiers undergo automated validation against jurisdictional rules, checksums, and standard formatting conventions.
- Policy Redaction: Configured data privacy policies trigger automatic visual obfuscation and metadata stripping for designated sensitive fields.
- Review & Export: Validated results and sanitized documents are exported directly to ERP/CRM systems, analytical stores, or downstream document repositories, with low-confidence items flagged for rapid human verification.
9. Who Benefits
10. Business Impact
11. Product Differentiation
12. Strategic Value
Implementing SensiAvera supports key enterprise modernization and governance initiatives:
- Global Expansion Readiness: Empowers businesses to enter new international markets without needing to re-engineer document verification pipelines or recruit region-specific back-office teams.
- Standardized Information Architecture: Establishes a single, structured data standard for all incoming documents, simplifying downstream analytics, data warehousing, and system interoperability.
- Proactive Risk & Privacy Governance: Embeds privacy-by-design principles directly into document processing pipelines, ensuring compliance evolves seamlessly alongside changing international regulations.
- Resilient Operational Scalability: Provides a scalable foundation capable of handling seasonal volume spikes and long-term organizational growth without sacrificing turnaround speed or data precision.
13. Closing Value Proposition
Cross-border document processing demands a balance between operational speed, extraction precision, and stringent data protection. SensiAvera bridges the gap between complex international document layouts and enterprise systems by combining comprehensive global coverage, spatial entity extraction, deterministic algorithmic validation, and automated visual redaction in a single, unified platform.
For organizations seeking to eliminate manual document processing costs, accelerate cross-border transaction cycles, and safeguard sensitive data across global jurisdictions, SensiAvera delivers the accuracy, efficiency, and compliance assurance necessary to drive modern business operations forward.
Caratteristiche principali
Casi d’uso
- Automated Customer Onboarding, Identity Verification & KYC / KYB Compliance
- Financial & Commercial Document Processing (Invoices, Tax Returns, Bank Statements)
- Automated Visual PII Masking & GDPR / PDPL Data Anonymization
- Cross-Border Trade, Logistics & Customs Entry Declaration Parsing (Master Bill of Lading, SAD)
- Legal & HR Document Processing (Payslips, Employment Contracts, Property Deeds)
Piani tariffari
Piani tariffari
Prodotti correlati

WaterMeter Snap
Autonomous optical meter OCR, rolling dial reader, real-time consumption telemetry, and predictive leak detection for residential and commercial water meters.

WarrantyKeeper
Autonomous receipt OCR, warranty expiration tracking, coverage disentanglement, and claim dossier generation for appliances and electronics.

Voice2Invoice
Autonomous speech-to-invoice transcription, multi-category line item disentanglement, and compliant B2B remittance sheet generation.